

Google Gemma 4 Review: 5 Reasons Developers Are Switching (Apache 2.0 & Benchmarks)


By Jin, Founder & Startups
, updated 7 min read
A Quiet Thursday That Changed the Open-Source Race
In the high-stakes theater of Large Language Models, Google’s Gemma family has occupied a curious position. Despite racking up 400 million downloads since 2024, enterprise adoption was often throttled by "strings attached" in the licensing. Developers loved the performance but feared the lack of true digital sovereignty.
On a quiet Thursday in April 2026, the landscape shifted. By stripping away restrictive usage terms and delivering "frontier-class" reasoning in localizable packages, Gemma 4 marks the moment Google stopped playing defensive and started leading the open-weight charge.
Apache 2.0 and the End of "Open-Weight" Ambiguity
For a Senior Strategist, the most critical update in Gemma 4 is the transition to the Apache 2.0 license. Previous iterations were hampered by the "Gemma Terms of Use," which included a controversial "remote access" clause. This allowed Google the authority to restrict or disable usage remotely if policies were violated, a non-starter for enterprises requiring air-gapped security or vendor lock-in mitigation.
By adopting Apache 2.0, Google has eliminated these custom carve-outs and the risk of post-deployment rule changes. Hugging Face CEO Clément Delangue correctly identified this as a "huge milestone" for developer flexibility. This is a guarantee of sovereignty for teams building in sensitive or high-compliance environments.
The "E" Models’ Silent Power-Play
The introduction of the "Effective" (E) models, specifically the E2B and E4B, redefines what is possible in VRAM-constrained environments. To understand the E4B, we must look at the math: it possesses 8.0 billion total parameters, yet only 4.5 billion are effective during compute.
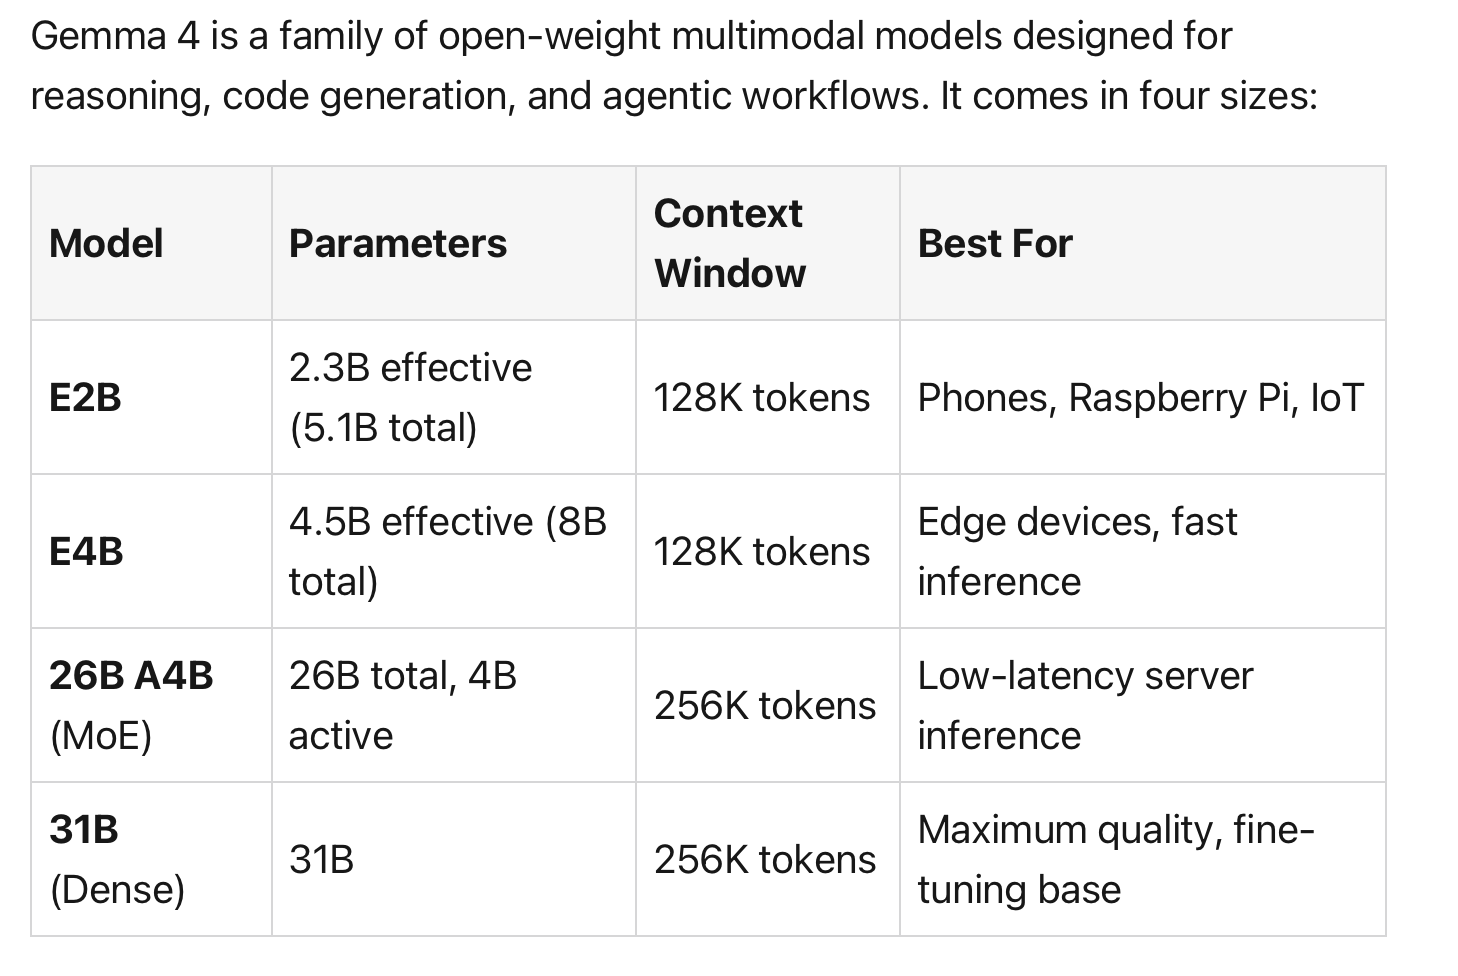
This efficiency is powered by Per-Layer Embeddings (PLE).
Rather than adding global parameters, PLE gives each decoder layer its own dedicated embedding table for every token. While this increases the static weight footprint (the VRAM required to hold the model), these tables are used only for lookups, keeping the active compute footprint remarkably low. This architecture allows these tiny models to process not just text and images, but native audio and video fully offline on hardware as humble as a Raspberry Pi or a smartphone, without the latency of bolted-on encoders.
Intelligence-per-Parameter: Beating Models 20x Larger
Google’s claim of "unprecedented intelligence-per-parameter" is validated by staggering gains in reasoning efficiency. The 31B Dense model now sits in the top tier of open models on the Arena AI leaderboard. Its 85.7% score on the GPQA Diamond benchmark (graduate-level science) is a formidable result, trailing Alibaba’s Qwen 3.5 27B (85.8%) by the narrowest of margins.
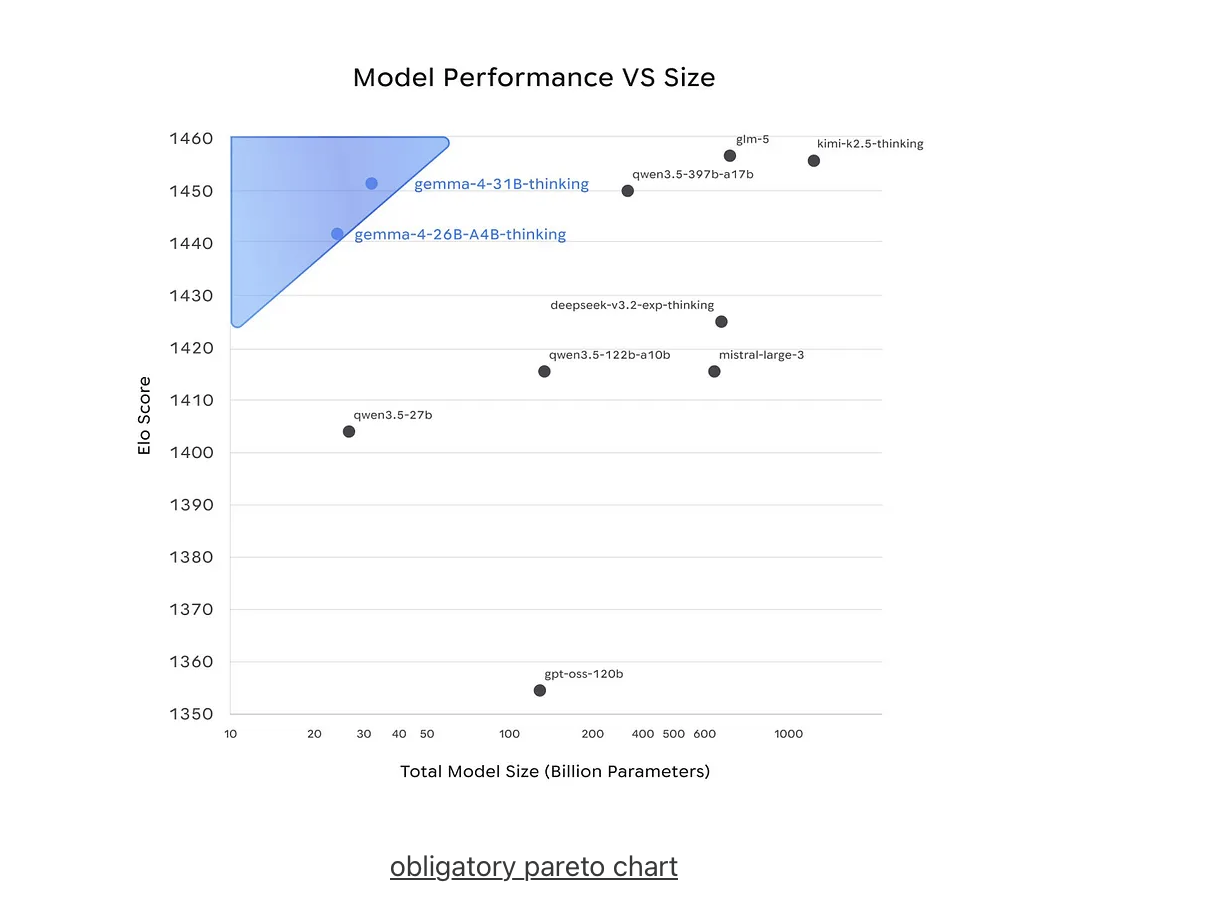
More impressive is the leap in mathematical reasoning: Gemma 3 27B managed a mere 20.8% on AIME, whereas Gemma 4 31B hits 89.2%—a 4x improvement in reasoning efficiency. This specialization is further showcased by TranslateGemma, a suite within the family that sets new standards for machine translation. By utilizing a two-stage SFT + RL pipeline with MetricX-QE and AutoMQM reward models, Google has proved that smaller, specialized models can outperform massive, generalist ones.
Mixture of Experts (MoE): 26B Logic at 4B Speed
The 26B A4B MoE architecture solves the industry’s most pressing trade-off: the cost of reasoning versus the speed of inference. This model utilizes 128 experts plus one always-active shared expert, with eight experts activated per token.
From a strategic perspective, hardware planning is key: while only ~3.8B–4B parameters are active for compute, the entire 26B weights must be loaded into memory (requiring approximately 48GB in BF16). For developers, this means the model offers the high-level logic and expansive knowledge of a 26B parameter system with the throughput efficiency of a 4B model, making it the ideal candidate for high-volume document processing and coding assistants.
The "Potato" Benchmark: High-Performance AI on a Raspberry Pi 5
The community’s "Potato" benchmarks provide the ultimate reality check for edge accessibility. Using a Raspberry Pi 5 with 16GB RAM, testers achieved a stable 4.52 tokens/second on text generation for the E2B-it Q8_0 model.
Achieving these production-usable speeds on a $100 SBC required a clever firmware tweak: a PCIe Gen3 override in the boot configuration to double the read speed of the attached M.2 SSD. This confirms that localized, private AI is no longer a luxury for those with H100 clusters; it is now a viable tool for IoT developers and hobbyists working on the workshop bench.
The Dawn of the Agentic Era
Gemma 4 is the first open-weight family designed specifically for the Agentic Era. With a 256K context window capable of ingesting entire codebases and a native Agent Development Kit (ADK), the platform is ready for autonomous workflows.
For the enterprise, the most high-impact feature is the GKE Agent Sandbox. This technology enables sub-second cold starts and can spin up to 300 sandboxes per second, allowing for the secure, isolated execution of LLM-generated code and tool calls at scale. With frontier-class reasoning now fitting on a local workstation—unencumbered by licensing restrictions—one must ask: Is the era of "closed-source" dominance effectively over?
Sources
- 1https://cloud.google.com/blog/products/ai-machine-learning/gemma-4-available-on-google-cloudcloud.google.com
- 2https://en.wikipedia.org/wiki/Gemma_(language_model)en.wikipedia.org
- 3https://www.thelec.net/news/articleView.html?idxno=6355thelec.net
- 4https://www.eweek.com/news/google-gemma-4-apache-2-open-models/eweek.com
- 5https://blog.google/innovation-and-ai/technology/developers-tools/gemma-4/blog.google
- 6https://wavespeed.ai/blog/posts/what-is-google-gemma-4/wavespeed.ai
- 7https://huggingface.co/blog/gemma4huggingface.co
- 8https://aibusiness.com/generative-ai/google-launches-open-model-family-gemma-4aibusiness.com
- 9https://www.ciodive.com/news/google-gemma-4-AI-model-open-source/816644/ciodive.com
- 10https://medium.com/data-and-beyond/google-gemma-4-explained-why-googles-apache-2-0-open-model-release-matters-for-local-ai-d5ba37b5b7eb#:~:text=Gemma%204%20is%20architected%20as,for%20efficient%20high%2Dthroughput%20reasoning.medium.com
- 11https://ai.google.dev/gemma/docs/coreai.google.dev
- 12https://ai.google.dev/gemma/docs/core/model_card_4ai.google.dev
- 13https://github.com/huggingface/blog/blob/main/gemma4.mdgithub.com
- 14https://unsloth.ai/docs/models/gemma-4unsloth.ai
- 15https://ai.rs/ai-developer/gemma-4-vs-qwen-3-5-vs-llama-4-comparedai.rs
- 16https://lmstudio.ai/models/gemma-4lmstudio.ai
- 17https://dev.to/arshtechpro/gemma-4-a-practical-guide-for-developers-2co5dev.to
- 18https://forums.developer.nvidia.com/t/gemma-4-day-1-inference-on-nvidia-dgx-spark-preliminary-benchmarks/365503forums.developer.nvidia.com
- 19https://www.reddit.com/r/LocalLLM/comments/1saktik/gemma4_someone_at_google_just_merged_a_pr_titled/reddit.com
- 20https://build.nvidia.com/google/gemma-4-31b-it/modelcardbuild.nvidia.com
- 21https://www.mindstudio.ai/blog/what-is-gemma-4-google-open-weight-modelmindstudio.ai
- 22https://android-developers.googleblog.com/2026/04/AI-Core-Developer-Preview.htmlandroid-developers.googleblog.com
- 23https://cloud.google.com/blog/products/ai-machine-learning/build-a-real-time-voice-agent-with-gemini-adkcloud.google.com
- 24https://ai.google.dev/gemma/docs/core/prompt-formatting-gemma4ai.google.dev
- 25https://ai.google.dev/gemma/docs/capabilities/thinkingai.google.dev
- 26https://deepmind.google/models/gemma/gemma-4/deepmind.google
- 27https://huggingface.co/unsloth/gemma-4-E4B-it-GGUFhuggingface.co
- 28https://developers.googleblog.com/bring-state-of-the-art-agentic-skills-to-the-edge-with-gemma-4/developers.googleblog.com
- 29https://www.youtube.com/watch?v=wgOCzHXKw4cyoutube.com
- 30https://google.github.io/adk-docs/tutorials/google.github.io
- 31https://medium.com/@mezzihoussem/building-local-agents-with-google-adk-gemma-and-ollama-%EF%B8%8F-5e84063f8eafmedium.com
- 32https://github.com/google/adk-samplesgithub.com
- 33https://www.reddit.com/r/LocalLLaMA/comments/1scucfg/gemma_4_26b_is_the_perfect_all_around_local_model/reddit.com
- 34https://www.reddit.com/r/LocalLLaMA/comments/1sc87tk/running_gemma_4_e4b_96gb_ram_req_on_rpi_5_8gb/reddit.com
- 35https://www.reddit.com/r/LocalLLaMA/comments/1sdcdno/benchmarks_of_gemma4_and_multiple_others_on/reddit.com
- 36https://www.analyticsvidhya.com/blog/2026/04/googles-gemma-4-open-source-model/analyticsvidhya.com
- 37https://medium.com/@borislavbankov/googles-gemma-4-just-made-cloud-ai-optional-30145cd35f62medium.com
- 38https://github.com/msb-msb/awesome-local-aigithub.com
- 39https://huggingface.co/docs/google-cloud/examples/vertex-ai-notebooks-fine-tune-gemma-4huggingface.co
- 40https://www.reddit.com/r/LocalLLaMA/comments/1sdcotc/gemma_4_just_casually_destroyed_every_model_on/reddit.com
- 41https://news.ycombinator.com/item?id=47638811news.ycombinator.com
- 42https://blog.google/innovation-and-ai/products/responsible-ai-2026-report-ongoing-work/blog.google
- 43https://ai.google/static/documents/ai-responsibility-update-2026.pdfai.google
- 44https://ai.google.dev/gemma/docsai.google.dev
- 45https://replicate.com/google-deepmind/shieldgemma-2-4b-it/readmereplicate.com
- 46https://docs.cloud.google.com/vertex-ai/generative-ai/docs/modelsdocs.cloud.google.com
- 47https://huggingface.co/nvidia/Nemotron-Content-Safety-Reasoning-4Bhuggingface.co
- 48https://arxiv.org/abs/2601.09012arxiv.org
- 49https://github.com/lhl/realitycheck-data/blob/main/analysis/sources/google-2026-translategemma-tech-report.mdgithub.com
- 50https://arxiv.org/pdf/2601.09012arxiv.org
- 51https://huggingface.co/google/translategemma-4b-ithuggingface.co
- 52https://github.com/alvinreal/awesome-opensource-aigithub.com